1. The problem
Agora is my self-directed product response: it is designed to take a business's feedback through a preset analysis pipeline into a dashboard where every proposed coding decision can be checked and changed. The current public evidence is a static replay of a real run plus a runnable local Docker bundle; there is no continuously hosted inference product and no customer yet.
The point of it is access. Thorough, checkable analysis of what people say about a business has been the preserve of organisations that can afford a research firm and wait weeks for the answer. Agora is built to put the same rigour inside a decision window, at a cost that lets a business run it routinely rather than once a year.
2. The traced run
- Ingest 1,643 Trustpilot and Skytrax reviews for Emirates.
- Generate 694 candidate themes from the raw text.
- Consolidate to 16 themes.
- Hierarchy, mapping and review surface: cluster the 16 into parent and leaf themes, map every review to a theme and a stance, and hand the result to the review screen below.
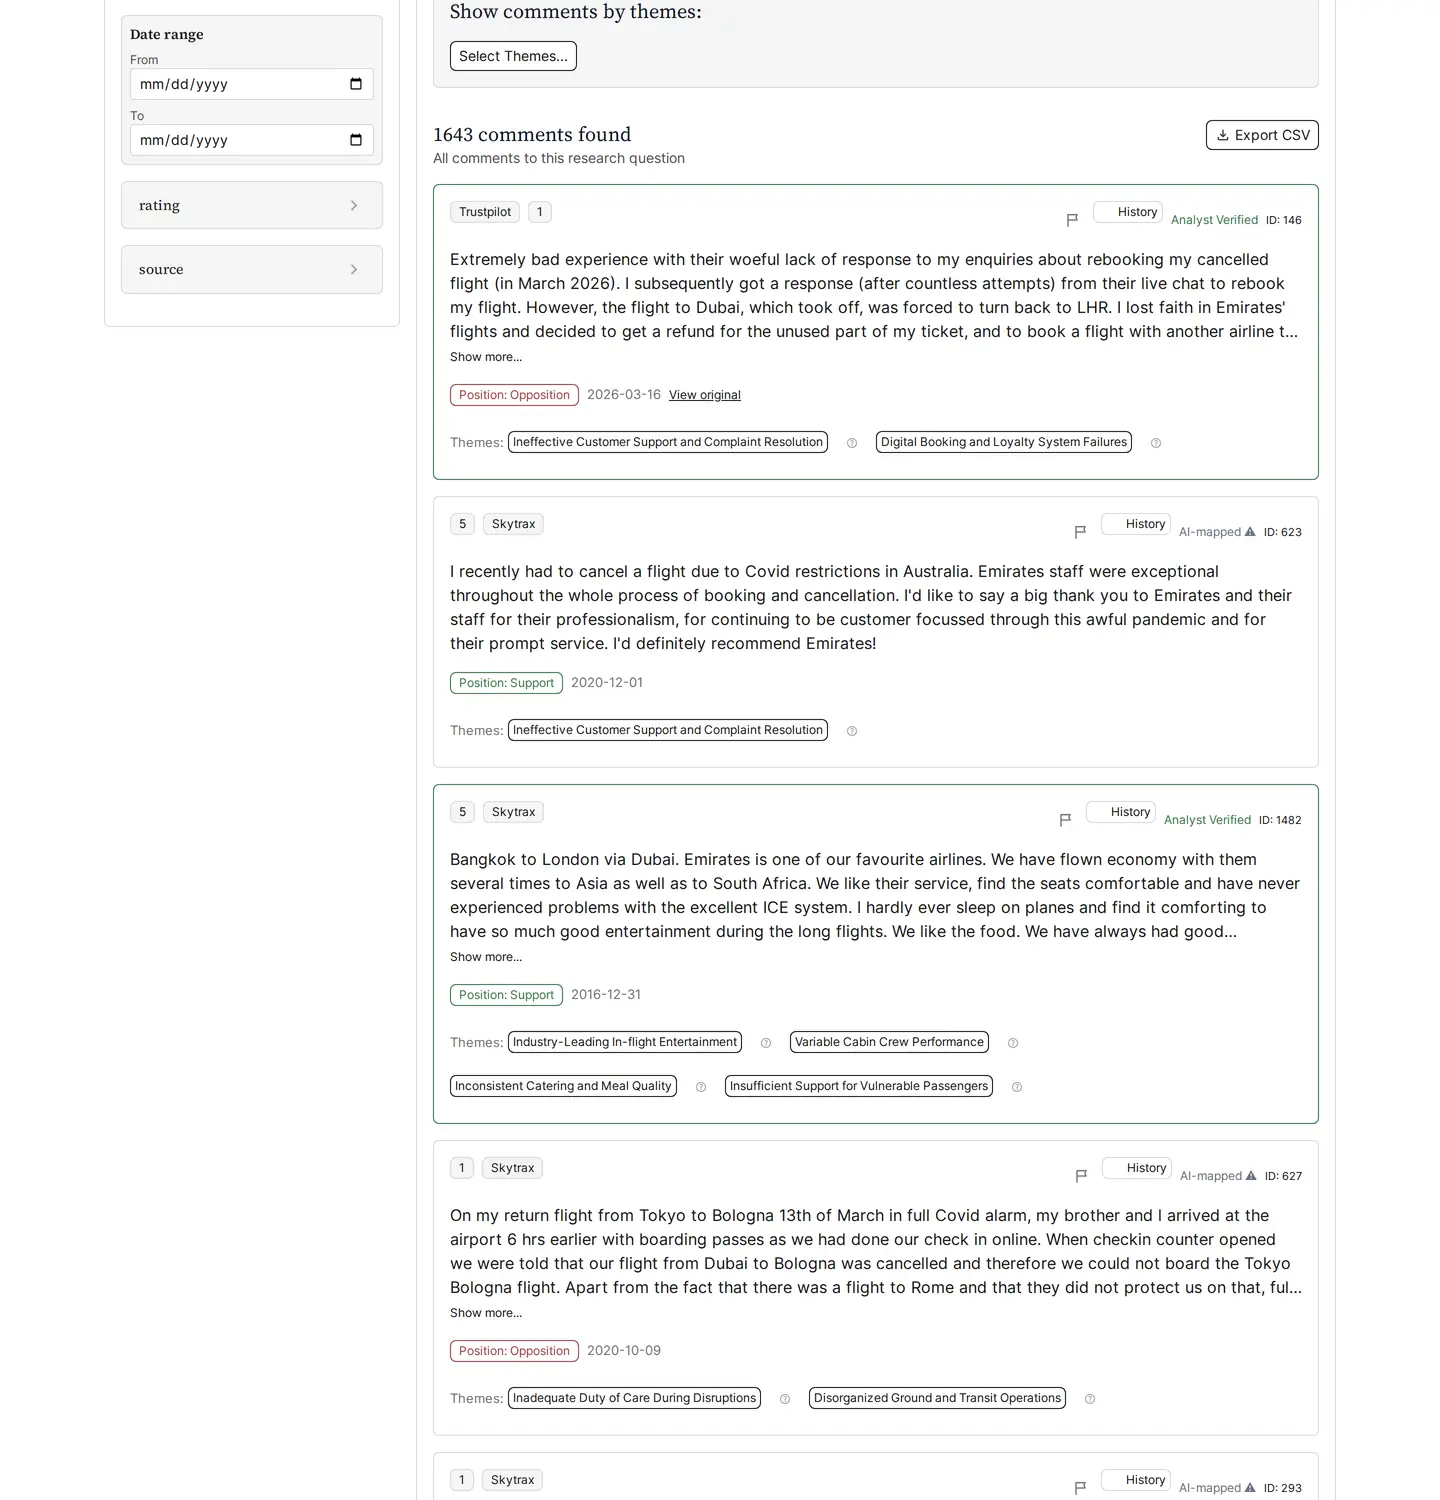
This is a real trace, not a mockup, and it is useful for judging throughput and the product surface rather than accuracy. No quality figure attaches to the public Emirates demonstration; the validation evidence sits in the provenance table below, from two different datasets entirely.
3. Where the numbers come from
Three datasets sit behind the numbers on this page. The engagement validation ranks first: 84.3% is theme recall against coding the research firm's analysts completed independently before the engine saw the data, the gap is over-assignment, and there is no single gold standard to be precise against. SemEval's discovery-mode detection micro-F1 of 0.8293 is second-rank evidence, scored in-house after 35 discovered themes were aligned to five gold categories, a step that took 11 human judgment calls. Emirates supports throughput and surface only.
| Dataset | Purpose | Supports | Limit |
|---|---|---|---|
| New Zealand legislative consultation | Independent engagement validation | 84.3% theme recall against the research firm's prior analyst coding | Gap was over-assignment; qualitative coding has no single gold standard |
| SemEval-2014 Task 4 · 800 restaurant-review sentences | In-house regression check on public academic data | Discovery-mode detection micro-F1 0.8293 after 35 discovered themes were aligned to five gold categories | 11 of 35 alignments required human judgment; scored by the builder; second-rank evidence behind client validation |
| Public Emirates reviews · Trustpilot and Skytrax | Throughput and product-surface demonstration | 1,643 reviews · 353 model calls · 22 minutes | No quality figure attaches to this run |
4. The product surface
Built to be inspected, not just watched. The public demo is a static replay of the traced run above, a captured walkthrough of the LLM-assisted onboarding wizard, and a tour of the dashboard it feeds: hierarchical themes, stance and sentiment, with every AI-proposed coding decision visible and correctable. A restricted build of the same application also ships as a runnable Docker bundle — clone it, run docker compose up, and the real dashboard, filtering and human-review flow come up against that same pre-analysed Emirates dataset, with the proprietary pipeline code excluded and a disclosed stub in its place.
Deployed solo. The VPS deployment system was built and exercised end to end: a Hetzner VPS behind a Caddy edge with automatic TLS, per-engagement Docker Compose stacks, a hardened host (key-only SSH, ufw, fail2ban), uptime monitoring, and cost-capped LLM runs so a demo could not run up an open-ended bill.
5. The engine: inherited and new
- Inherited
- The configurable, up-to-nine-step analysis pipeline behind Stoa, its hierarchical theme clustering, mapping that climbs leaf → parent → an explicit OTHER instead of forcing a bad fit, and the review discipline that puts every AI-proposed decision in front of a human before it counts. The Stoa case study covers how each of those was built and validated.
- New
- Commercial-feedback defaults in place of consultation-analysis ones, the onboarding wizard, the public static replay, Docker packaging for a restricted build, and the deployment tooling that runs it.
The sovereignty stack does not carry over. Self-hosted open-weight inference existed to meet a government data-residency requirement. Agora has no such requirement and does not run that way.
Why cheap models are enough. Those guardrails were built for open-weight models a government client could self-host, well below a frontier API's ceiling. The by-product is that the same structure still carries cheap, fast models now that it doesn't have to: the class that includes Gemini Flash, Claude Haiku and the OpenAI mini tier, where a million input tokens costs about a dollar, which is what keeps a full 800-text discovery pass priced in cents rather than dollars.
Why orchestration beats a bigger model. Handing the whole corpus to one frontier model and asking for themes fails in ways the business can't see: themes drift between runs, long inputs get skimmed, nothing traces back to a specific response, and the bill scales with the corpus. Structure is what closes that gap: staged phases with defined inputs and outputs, prompts that encode a documented analysis method, batches sized to the model's context, and de-duplication and clustering as explicit steps rather than something you hope happens inside the model. Run the same corpus twice and you get the same shape of answer, with every theme traceable to the responses behind it.
What that costs in practice. In the public traced run, four stages touch every row: sentiment, theme generation, theme mapping and detail detection. That is four passes over 1,643 reviews, roughly 6,600 row-level coding decisions, in 353 model calls. The remaining stages work on the theme list rather than the reviews, condensing 694 candidate themes to 16, so the model is spent only where a decision has to be made. Off-the-shelf AI-assisted analysis tooling in this space runs to the order of tens of thousands of dollars per engagement, by my estimate a large share of it model API cost passed straight through. That gap is not a better model. It is orchestration: batching, staging, and tokens spent where they count. The call count is a throughput and efficiency figure, not a quality one.
6. Evidence
- agora.fridai.dev, the case-study demo site
- agora-demo on GitHub, the runnable Docker bundle
- Exhibit 11: per-engagement VPS deploy (Caddy + Docker, multi-tenant isolation)
- Exhibit 12: Docker image leak scanner (proves the pipeline stub, not the real code, ships in the public bundle)
- Capabilities register, every claim on this page traced to evidence